OCR
io.github.lamplis:vision-ocr is built by :vision-ocr. The Kotlin package is io.github.lamplis.vision.ocr. createOcr() reads an encoded image and returns OcrLines. Each boundingBox is a top-left NormalizedRect (left, top, right, bottom). Android uses ML Kit text recognition. iOS uses Vision VNRecognizeTextRequest. visionBottomLeftToTopLeft maps a Vision box into that top-left rect; callers of createOcr() already receive top-left boxes. The approach follows Compose Multiplatform Text Recognition by Amirhossein Ijadi. That repository is not copied into this one.
val recognizer = createOcr()
val lines = recognizer.recognize(jpeg)
lines.forEach { line ->
    val box = line.boundingBox
    println("${line.text} ${box.left},${box.top} ${box.right},${box.bottom}")
}
recognizer.close()
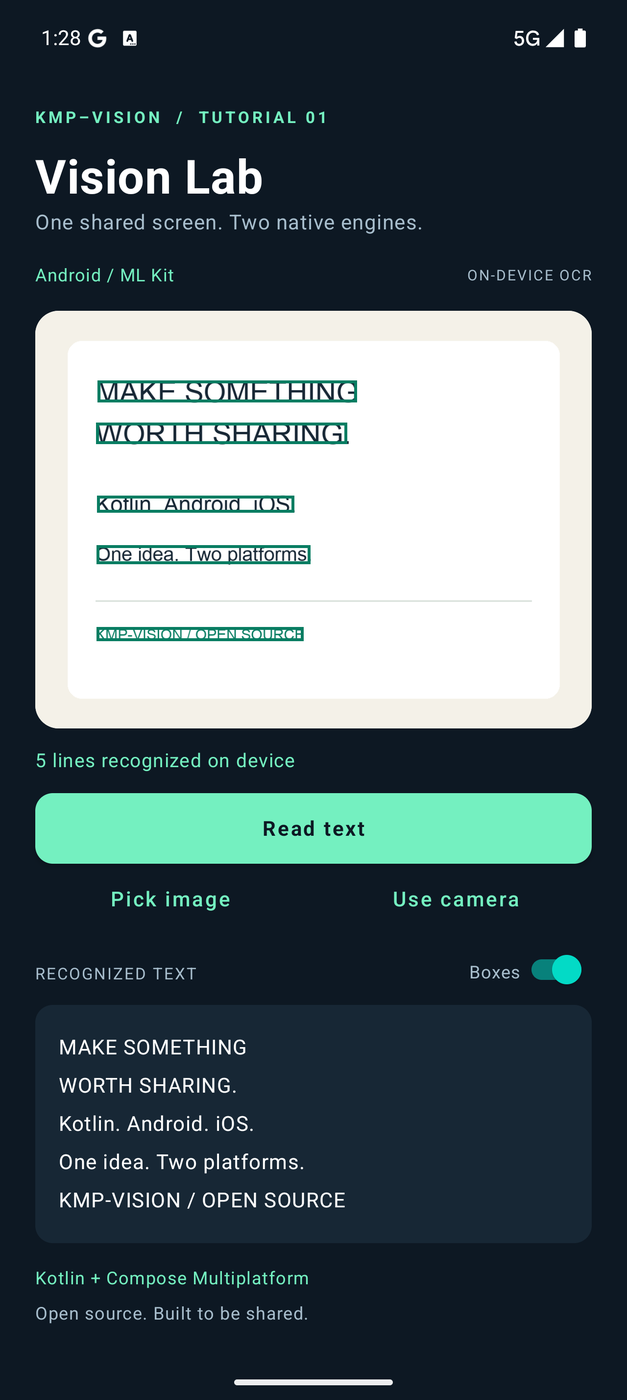
Captured from Vision Lab, the runnable tutorial.
Platform behavior
Android currently uses ML Kit’s Latin text recognizer; the recognitionLanguages argument is ignored on Android. iOS passes language preferences to Apple Vision. Text segmentation, confidence values, and recognized output may differ between engines. The tutorial screenshots show these differences using the same input image.